HAMi AI Platform Air-Gapped Deployment Guide
This document is intended for SRE / platform engineers. It describes how to deploy HAMi AI Platform in a Kubernetes cluster using the v0.0.6 All-in-One air-gapped package and Zarf v0.86.0, then complete license activation, accelerator node enablement, and sample workload validation. Commands use Linux amd64; replace the filenames for arm64 deployments. PPU components are included only in amd64 packages.
This delivery package uses Zarf to perform image import, Helm chart installation, and subsequent upgrades in environments without external network access or with restricted networks, reducing the manual effort of syncing images and maintaining installation order.
Zarf is an application packaging and deployment tool for Kubernetes air-gap / semi-air-gap environments; it can bundle images, Helm charts, scripts, and deployment actions into a portable package.
Installation itself does not require a license. Complete the software deployment first, then apply for and import the license.
Without activation, vGPU partitioning and scheduling are unavailable, and functional verification will fail.
Air-Gapped Package Contents
This guide targets Chart 0.21.3 for the HAMi AI Platform (Kantaloupe) component. The air-gapped package version remains v0.0.6, so the filename alone does not identify the bundled Chart version. Before deployment, confirm with your delivery contact that the supplied package includes Chart 0.21.3, and use the SHA-256 checksum file supplied with that package. If the package still contains an older Chart, obtain an updated air-gapped package; editing package-values.yaml does not upgrade the bundled Chart.
The outer delivery package naming convention is:
The examples use v0.0.6, amd64, and the full package. The Slim archive is hami-ai-platform-slim-v0.0.6-airgap-amd64.tar.gz. Slim retains GPU Operator but omits NVIDIA driver images and sample workloads. Its GPU nodes must already have a compatible NVIDIA driver.
hami-ai-platform-v<VERSION>-airgap-<ARCH>.tar.gz
hami-ai-platform-v<VERSION>-airgap-<ARCH>.tar.gz.sha256
The current hami-ai-platform-v0.0.6-airgap-amd64.tar.gz contains the following key files:
| File | Purpose |
|---|---|
zarf-linux-amd64 | Linux amd64 Zarf CLI |
zarf-init-amd64-v0.86.0.tar.zst | Zarf init air-gapped package |
hami-ai-platform-v0.0.6-airgap-amd64.tar.zst | HAMi AI Platform main deployment package |
zarf-package-hami-example-gpu-burn-amd64-v0.0.2.tar.zst | GPU burn sample validation package |
zarf-package-hami-example-vllm-qwen-amd64-v0.0.4.tar.zst | vLLM + Qwen sample validation package |
kantaloupe/ | kantaloupe values examples and full values documentation |
hami/README.md | hami-enterprise full values documentation |
collect-hami-license-info.sh | License application information collection script |
collect-cluster-info.sh | Cluster diagnostic information collection script |
package-values.yaml | Component-scoped package values template |
PACKAGE-VALUES.md | Component mapping and values migration guide |
COLLECT-CLUSTER-INFO.md | Cluster information collector instructions |
Prerequisite Checks
| Type | Requirement | Verification Command |
|---|---|---|
| Kubernetes | The v0.0.6 air-gapped package requires Kubernetes ≥ 1.27 and an available default StorageClass. Selecting rpm requires Kubernetes ≥ 1.30. | kubectl version |
| Container runtime | A Kubernetes CRI runtime such as containerd or CRI-O; NVIDIA Container Toolkit configured on GPU nodes. | kubectl get nodes -o wide |
| GPU driver | NVIDIA driver ≥ 470 (recommended: ≥ 550) | nvidia-smi |
| Prometheus CRDs | Prometheus or VictoriaMetrics integration requires monitoring.coreos.com CRDs. Select prometheus-crds to install them from the package. | kubectl api-resources --api-group=monitoring.coreos.com |
| GPU Operator | If GPU Operator is already installed, disable its built-in device plugin and CDI to avoid conflicts with this HAMi Enterprise deployment. Full and Slim packages both retain gpu-operator. Slim omits NVIDIA driver images, so GPU nodes must already have a compatible driver. | zarf tools helm list -A |
| Disk space | More than 30 GB recommended | df -h |
Do not enable HAMi’s NVIDIA device plugin and GPU Operator’s built-in device plugin at the same time. Direct Helm configuration uses devicePlugin.enabled=false; v0.0.6 package values use gpu-operator.devicePlugin.enabled=false, which is already disabled in the package. The cluster also needs an available default StorageClass.
Extract, Verify, and Install Zarf
v0.0.6 has been published to OSS. Download the package and matching SHA-256 checksum file from the OSS URLs in the delivery record. This version has not yet been uploaded to R2; do not use R2 URLs to download v0.0.6.
# Download delivery package and checksum file
curl -L -O <URL>
curl -L -O <SHA256_URL>

# Verify integrity
shasum -a 256 -c hami-ai-platform-v0.0.6-airgap-amd64.tar.gz.sha256

# Extract outer tar.gz
tar -xzf hami-ai-platform-v0.0.6-airgap-amd64.tar.gz

# Enter extracted directory
cd hami-ai-platform-v0.0.6-airgap-amd64
The package includes the Linux Zarf v0.86.0 CLI and its matching init package. The example below uses amd64; for arm64, use zarf-linux-arm64 and the arm64 init package. Install the bundled CLI after entering the extracted directory:
chmod +x ./zarf-linux-amd64
sudo install -m 0755 ./zarf-linux-amd64 /usr/local/bin/zarf
zarf version
Zarf includes the Helm tool. For subsequent troubleshooting of Helm release, values, and chart status, use zarf tools helm to avoid relying on a separately installed Helm in the target environment:
zarf tools helm version
zarf tools helm list -A
Initialize Zarf
Run zarf init only if the target cluster has not been initialized. Use the labeled policy to limit image rewriting to explicitly labeled namespaces or workloads. For an existing Zarf installation, inspect its Registry, StorageClass, and Agent mutation policy first; deploying the main package does not change that policy.
Use the Zarf built-in registry:
zarf init zarf-init-amd64-v0.86.0.tar.zst \
  --agent-mutation-policy=labeled \
  --confirm
Use an external registry:
zarf init zarf-init-amd64-v0.86.0.tar.zst \
  --agent-mutation-policy=labeled \
  --registry-url=harbor.example.com/zarf-amd64 \
  --registry-push-username=<username> \
  --registry-push-password=<password> \
  --confirm
💡 Mixed-architecture clusters must use separate registry prefixes. AMD64 and ARM64 clusters may share the same Harbor instance, but they must not share the same Zarf registry project or repository prefix. Images in a Zarf air-gap package are packaged for the target architecture. Deploying AMD64 and ARM64 packages sequentially to the same image path does not merge identical tags into a multi-platform manifest. A later push may replace the earlier tag and cause Pods on the other architecture to pull an incompatible image after a restart or rescheduling.
During cluster initialization, use an architecture-specific
--registry-urlfor each architecture. For example, useregistry.example.com/zarf-amd64for AMD64 andregistry.example.com/zarf-arm64for ARM64. Create the corresponding Harbor projects or repository prefixes in advance, and ensure that the account used by Zarf has push and pull permissions.
External registry parameter descriptions:
| Parameter | Description |
|---|---|
--registry-url | External image registry address |
--registry-push-username | Username used to push images |
--registry-push-password | Password used to push images |
After initialization, zarf package deploy imports the images bundled in the package and uses an admission webhook to rewrite image references for managed workloads to the Zarf registry. With the labeled policy, only resources labeled zarf.dev/agent: mutate, or resources in a namespace with that label, are processed; a label on the resource takes precedence over the namespace label. Before deployment, confirm that the namespaces for the selected components have this label. For offline workloads created separately, confirm that the namespace is labeled first. Label changes do not affect existing Pods; recreate the Pods to trigger rewriting.
Use --insecure-skip-tls-verify for the relevant command only when the TLS certificate of the target registry genuinely cannot be verified and the man-in-the-middle risk has been assessed. In production, fix the certificate chain or configure a trusted CA for the Zarf Agent instead of treating skipped TLS verification as a default.
Deploy HAMi AI Platform
The package has no required components; all components are disabled by default. Select the components needed for the deployment with --components. Adding values for a component does not select it for installation.
Component list:
| Component Name | Description | Required | Recommended |
|---|---|---|---|
tools | Operations tools: jq and nerdctl. collect-hami-license-info.sh requires jq; without it, the script cannot collect the information needed to issue a license. | No | Recommended |
hami | HAMi Enterprise Chart 2.10.0-r4 | No | Yes |
rpm | Resource pool management; CRD Chart 0.4.2, manager Chart 0.0.6, manager image v0.0.2 | No | When resource pool management is needed and prerequisites are met |
ascend-device-plugin | Ascend Device Plugin; Chart 0.2.2, plugin v1.4.2 | No | As needed for Ascend clusters |
ppu-device-plugin | PPU Device Plugin and monitoring; Chart 0.0.5, plugin v1.0.6; amd64 only | No | As needed for PPU clusters |
npu-exporter | Ascend NPU metrics collection | No | When NPU metrics are needed |
prometheus-crds | Prometheus Operator CRDs | No | When installing the bundled Prometheus stack |
prometheus | kube-prometheus-stack Helm Chart | No | As needed |
gpu-operator | NVIDIA GPU Operator | No | As needed for NVIDIA; Slim requires a preinstalled compatible driver |
envoy-gateway-crds | Gateway API and Envoy Gateway CRDs | No | When enabling the platform Gateway |
envoy-gateway | Envoy Gateway | No | When enabling the platform Gateway |
hami-ai-platform | HAMi AI Platform (Kantaloupe); target Chart 0.21.3 | No | Yes |
envoy-gateway-crds uses fixed manifests rendered from the official Envoy Gateway v1.6.2 CRD chart. Outside the Helm release, it manages 12 Gateway API v1.4.1 Experimental CRDs and 8 Envoy Gateway CRDs through Server-Side Apply, avoiding the Kubernetes 1 MiB limit for Helm release Secrets caused by large CRDs. If Gateway API is already installed in the target cluster, the existing version is left unchanged, but all 12 required CRDs are checked. Envoy Gateway CRDs are updated idempotently and the deployment waits until they reach Established. envoy-gateway uses a copy of the official main chart with crds/ removed, preventing duplicate CRD installation or downgrades.
Zarf v0.86.0 supports --values directly. Starting with main package v0.0.5, configuration must be placed under the matching component key. Single-Chart components pass their configuration directly to the corresponding Chart; rpm.crds and rpm.manager configure the two RPM Charts separately. Precedence is Chart defaults → in-package valuesFiles → the corresponding component’s package values. Command-line overrides also need the full component path, for example --set-values hami.scheduler.leaderElect=true.
Tools, Prometheus CRD, and Envoy Gateway CRD components have no Chart values mapping. Platform authentication and ingress use hami-ai-platform.auth and hami-ai-platform.gateway. Configure the Envoy Gateway controller under the separate envoy-gateway key.
Prepare custom values
Start from package-values.yaml in the outer archive and follow PACKAGE-VALUES.md to configure the components that need overrides. Each Chart configuration path defaults to an empty object; omit --values if no overrides are needed. Root-level keys such as scheduler, nodeSelector, and global from v0.0.4 or earlier are not passed to Charts in v0.0.5 or later main packages. Move each setting under its target component key.
hami-enterprise values
Start with the package’s package-values.yaml template; see PACKAGE-VALUES.md for full instructions. Each component has an independent configuration path:
| Package Values Path | Target Chart / Availability |
|---|---|
hami | HAMi Enterprise; Enterprise and AI Platform |
rpm.crds / rpm.manager | HAMi Enterprise CRDs / Resource Pool Manager; Enterprise and AI Platform |
ascend-device-plugin | Ascend Device Plugin; Enterprise and AI Platform |
ppu-device-plugin | PPU Device Plugin; Enterprise and AI Platform, amd64 only |
npu-exporter | NPU Exporter; Enterprise and AI Platform |
prometheus | kube-prometheus-stack; Enterprise and AI Platform |
gpu-operator | NVIDIA GPU Operator; configurable in both full and Slim packages |
envoy-gateway | Envoy Gateway; AI Platform only |
hami-ai-platform | Kantaloupe; AI Platform only |
| Parameter | Description | Default |
|---|---|---|
hami.dra.enabled | Whether to enable and deploy DRA | false |
hami.scheduler.leaderElect | Whether to enable leader election for hami-scheduler across multiple nodes. Strongly recommended to disable for single-node clusters. | true |
hami.scheduler.replicas | Adjust the number of hami-scheduler instances | 1 |
hami.scheduler.kubeScheduler.image.registry | Image registry for the kube-scheduler image used by hami-scheduler | registry.cn-hangzhou.aliyuncs.com |
hami.scheduler.kubeScheduler.image.repository | Image repository name for the kube-scheduler image used by hami-scheduler | google_containers/kube-scheduler |
hami.scheduler.kubeScheduler.image.tag | Version of the kube-scheduler image used by hami-scheduler; should match the target cluster | "" |
Minimal package-values.yaml example. For a single-node cluster, set hami.scheduler.leaderElect to false:
hami:
  dra:
    enabled: false
  scheduler:
    leaderElect: false
For non-NVIDIA devices, enable the corresponding vendor under hami.devices. For Ascend, set both switches:
hami:
  devices:
    ascend:
      enabled: true
      hamiVnpuCore: true
The kube-scheduler image selected by HAMi must be included in the delivered package and imported into the registry chosen at zarf init. Zarf-managed workloads in hami-system have their image references rewritten by the Agent. Setting a different registry in values does not add a missing image to the package. If the target Kubernetes version requires another image, contact technical support for a matching package.
This bundle includes only kube-scheduler:v1.37.0. HAMi selects a scheduler image tag for the target Kubernetes version by default. If the target cluster requires another version, obtain a delivery package containing the matching image and verify that the target offline registry can serve it. Changing only the image tag does not add an image to the package. Override the registry, repository, and tag under hami.scheduler.kubeScheduler.image when needed.
When migrating from v0.0.4 or earlier, bare root-level keys such as scheduler, nodeSelector, and global are no longer passed to Charts. Move each Chart’s configuration under its component key; apply the same conversion to examples in hami/ and the platform’s kantaloupe/ directory. To migrate HAMi configuration only:
zarf tools yq '{"hami": .}' hami-current-values.yaml > package-values.yaml
Configure keys previously shared by several Charts separately. For example, Prometheus Operator uses prometheus.prometheusOperator, and Kantaloupe uses hami-ai-platform.
kantaloupe values
The in-package kantaloupe/README.md documents the full Chart values. The examples below and the in-package kantaloupe/ and hami/ examples use native Chart values. For the Zarf v0.0.6 main package, place them under hami-ai-platform and hami, respectively. Direct Helm installation still uses the native Chart structure. Root-level settings such as auth and gateway shown below cannot be used directly as package values.
kantaloupe provides settings for feature flags, service exposure, and monitoring integration. Configure them as required. For the complete values reference, see kantaloupe Helm Chart Values Reference.
For v0.0.6 air-gap deployment, place Kantaloupe settings under hami-ai-platform in package-values.yaml. Configure the Envoy Gateway controller under the separate top-level envoy-gateway key.
- Configure default platform administrator credentials
auth:
jwtSecret: "<JWT_SIGNING_SECRET>"
bootstrapAdminUsername: "bootstrap-platform-admin"
bootstrapAdminPassword: "<ADMIN_PASSWORD>"
bootstrapAdminFullName: "Platform Administrator"
- Expose Envoy Gateway through a NodePort Service and use an external load balancer (cloud-managed or self-managed) to forward Layer 4 traffic .
gateway:
  enabled: true
  hostnames:
    - your-domain.example.com
  apiserverCors:
    enabled: true
    allowCredentials: true
    allowOrigins:
      - https://your-domain.example.com
  envoy:
    service:
      ports:
        http:
          nodePort: 30080
        https:
          nodePort: 30443
      type: NodePort
  listeners:
    - name: http
      port: 80
      protocol: HTTP
    - name: https
      port: 443
      protocol: HTTPS
      tls:
        certificateRef:
          name: your-domain-tls-secret
        redirectFromHttp: true
- Use Envoy Gateway with a NodePort Service for a simple PoC
gateway:
  enabled: true
  listeners:
    - name: http
      port: 80
      protocol: HTTP
  envoy:
    service:
      type: NodePort
      ports:
        http:
          nodePort: 30080
- Use a LoadBalancer Service managed by a cloud provider or bare-metal load balancer controller
gateway:
  enabled: true
  hostnames:
    - your.domain
  listeners:
    - name: http
      port: 80
      protocol: HTTP
    - name: https
      port: 443
      protocol: HTTPS
      tls:
        certificateRef:
          name: your-tls-secret
        redirectFromHttp: true
  envoy:
    service:
      type: LoadBalancer
      ports:
        http: {}
        https: {}
- Override the Prometheus Query API address (default:
http://prometheus-kube-prometheus-prometheus.monitoring.svc.cluster.local:9090)
apiserver:
  prometheusAddr: http://your-prometheus-query-api.com:9090

controllerManager:
  prometheusAddr: http://your-prometheus-query-api.com:9090
Save the configuration as package-values.yaml. This example configures HAMi, platform authentication, and the platform Gateway separately; adjust it for the target environment and replace the authentication placeholders before deployment:
hami:
  dra:
    enabled: false
  scheduler:
    leaderElect: true

hami-ai-platform:
  auth:
    enabled: true
    jwtSecret: "<JWT_SIGNING_SECRET>"
    bootstrapAdminUsername: "<ADMIN_USERNAME>"
    bootstrapAdminPassword: "<ADMIN_PASSWORD>"
  gateway:
    enabled: true
    listeners:
      - name: http
        port: 80
        protocol: HTTP
    envoy:
      service:
        type: NodePort
        ports:
          http:
            nodePort: 30080
  hamiNamespace: hami-system
To review custom values, inspect the values and rendered manifests using the same --components and --values that you will use for deployment. This example selects HAMi, Gateway and AI Platform. Add optional hardware and monitoring components only when needed.
zarf package inspect values-files hami-ai-platform-v0.0.6-airgap-amd64.tar.zst \
  --components=hami,envoy-gateway-crds,envoy-gateway,hami-ai-platform \
  --values=package-values.yaml
zarf package inspect manifests hami-ai-platform-v0.0.6-airgap-amd64.tar.zst \
  --components=hami,envoy-gateway-crds,envoy-gateway,hami-ai-platform \
  --values=package-values.yaml
Execute Deployment
For a first AI Platform installation, select HAMi core, Gateway CRDs, Envoy Gateway, and HAMi AI Platform. If HAMi Enterprise is already installed, use the incremental command below. Select resource pool management, GPU Operator, Ascend, PPU, and monitoring components separately as needed. PPU is included only in amd64 packages.
zarf package deploy hami-ai-platform-v0.0.6-airgap-amd64.tar.zst \
  --components=hami,envoy-gateway-crds,envoy-gateway,hami-ai-platform \
  --values=package-values.yaml \
  --confirm
If the cluster already has HAMi Enterprise deployed, you only need to add Gateway and AI Platform afterward:
zarf package deploy hami-ai-platform-v0.0.6-airgap-amd64.tar.zst \
  --components=envoy-gateway-crds,envoy-gateway,hami-ai-platform \
  --values=package-values.yaml \
  --confirm
If a component takes a long time to complete, first identify whether it is importing images, running Helm hooks, or waiting for workload health checks. Diagnose the issue with zarf tools helm, Pod events, and logs. For incorrect values, fix the corresponding configuration in package-values.yaml, inspect it again, and rerun the same deployment command. If the operation exceeds the default 15 minutes, determine the cause before adjusting --timeout.
After an interrupted deployment, resolve the issue and resume with the same zarf package deploy ... --components=... --values=... command. Zarf will skip re-importing images when the digest has not changed; it will perform a Helm upgrade when Helm charts or values have changed.
If the target resources are already managed by another Helm release and you have confirmed that they should be transferred to the current Zarf package, review the resource scope and then use --take-ownership. Use --force-conflicts only for Server-Side Apply field ownership conflicts. It overwrites fields managed by other field managers, so use it only after confirming that this deployment may take over those fields; do not use it as a general retry option.
Optional: NVIDIA GPU Operator
GPU Operator is optional, as are the Ascend components below. Skip it when the nodes already have a compatible driver, NVIDIA Container Toolkit and runtime configuration. See the HAMi NVIDIA GPU node prerequisites for the detailed Operator values. Do not enable CDI: this HAMi Enterprise deployment uses scheduler.useDownward. The bundled Operator has CDI and its own device plugin disabled. Slim retains GPU Operator, but its GPU nodes must already have compatible drivers.
zarf package deploy hami-ai-platform-v0.0.6-airgap-amd64.tar.zst \
  --components=gpu-operator \
  --values=package-values.yaml \
  --confirm
Enable GPU Nodes
The HAMi NVIDIA device plugin starts on nodes labeled gpu=on. Apply this label to NVIDIA nodes that HAMi should manage. Ascend components use their own nodeSelector; gpu=on is not their selection rule.
kubectl label nodes <node-name> gpu=on
Optional: Ascend Components
ascend-device-plugin and npu-exporter are optional components disabled by default. They support amd64 and arm64 and can be selected in Enterprise, AI Platform, and their Slim packages. This package uses Ascend Device Plugin Chart 0.2.2 and plugin v1.4.2. The plugin runs in hami-system and uses the existing hami-scheduler-device ConfigMap; the Exporter runs in the npu-exporter Namespace. Avoid duplicate installations. Ascend-only clusters do not need GPU Operator; select hardware components as needed for mixed-device clusters.
Prepare the Nodes
NPU Exporter supports ordinary Ascend compute nodes using containerd. Install the driver, firmware, and runtime on each target node first. Atlas 200I SoC A1 core boards require separate upstream manifests and startup scripts and are outside this component’s scope.
The default selector reuses the plugin’s ascend: "on" node label. No separate Exporter label is needed. The default containerd directory is /run/containerd. Override the Exporter settings only if the actual node labels or runtime path differ.
The installer creates the Exporter log directory and sets ownership to root:root and mode 0750. No manual directory setup on each node is needed. Installation uses the standard Zarf and Helm readiness checks. Verify metric collection and monitoring integration as described under “Verify the Deployment” below.
Configure and Deploy
The default node labels and containerd path need no extra configuration. Keep HAMi settings aligned with the target NPU model and partitioning mode. For a non-default containerd path, configure npu-exporter.hostPaths.containerd with the path used by the target nodes.
To add these components to a cluster where HAMi is already installed, select them as below. For a first installation, add them to the component combination for your edition. Also select prometheus-crds,prometheus when using the bundled monitoring stack. Use the main package for the selected version and architecture.
zarf package deploy <main-package.tar.zst> \
  --components=ascend-device-plugin,npu-exporter \
  --values=package-values.yaml --confirm
Omit --values if no overrides are needed. Select only npu-exporter if the plugin is already installed. Image changes require rebuilding the package with the new image; an offline deployment cannot pull an image that was not packaged.
Connect Monitoring
Clusters managed by Kantaloupe: The Exporter does not create a ServiceMonitor by default. Kantaloupe manages local and member-cluster scraping. The Service in npu-exporter uses the labels and port expected by the platform template, so no custom scrape manifest is needed.
Whenever a data-plane cluster introduces a new device vendor, enable that vendor’s monitor switch in the control-plane Kantaloupe values and run Helm upgrade. Use the following configuration for Ascend, even when the control plane has no Ascend devices: it also enables the recording rules needed for member-cluster metrics. For Zarf, nest the configuration under hami-ai-platform; for a direct Helm upgrade, omit that outer key and preserve the existing configuration.
hami-ai-platform:
  monitoring:
    enabled: true
    vendorServiceMonitor:
      enabled: true
      enableAscendServicemonitor: true
Standalone monitoring without Kantaloupe: Enable the Exporter’s optional ServiceMonitor. When using the bundled stack, install prometheus-crds,prometheus. After deployment, confirm the targets and metrics in Prometheus. Avoid two monitors scraping the same Exporter.
npu-exporter:
  serviceMonitor:
    enabled: true
Verify the Deployment
kubectl -n hami-system get daemonsets
kubectl -n npu-exporter get daemonset npu-exporter
kubectl -n npu-exporter rollout status daemonset/npu-exporter --timeout=180s
kubectl -n npu-exporter get pods -o wide
kubectl -n npu-exporter get endpointslice -l kubernetes.io/service-name=npu-exporter
Check the Exporter DaemonSet’s DESIRED and READY counts: both should equal the expected number of Ascend nodes and be greater than zero. Query up{job="npu-exporter",namespace="npu-exporter"} and npu_chip_info_utilization in Prometheus to confirm scraping and metrics for each node. Zero utilization is valid for idle devices. Also verify device-plugin registration and run a workload requesting the expected Ascend resources to confirm allocation and device access.
For Kantaloupe, query the member cluster’s raw npu_chip_info_* metrics and normalized kantaloupe_gpu_core_used{vendor="ascend",cluster="<member-cluster-name>"} metrics on the control plane. Exporter Pods being Ready does not prove federation and platform monitoring are connected. Prometheus configuration updates and the first scrape take some time after a ServiceMonitor is created. If metrics are missing, check the driver and DCMI. For scrape failures, check target discovery, configuration reload, ServiceMonitor labels, duplicate scraping, and network policies.
Maintenance and Non-default Environments
For Exporter troubleshooting, check that the node has a usable containerd.sock at the configured containerd directory. The component mounts the directory, rather than an individual socket file.
The NetworkPolicy allows TCP 8082 from Pods labeled app.kubernetes.io/name: prometheus across namespaces and denies outbound traffic by default; enforcement depends on the CNI. For other monitoring labels, override npu-exporter.networkPolicy.prometheusPodSelector. Configure standalone ServiceMonitor selector labels through npu-exporter.serviceMonitor.labels.
The Exporter runs as root in a privileged container and accesses host driver libraries, DCMI libraries, and the runtime socket. A read-only socket mount does not restrict runtime API calls. Keep DCMI libraries and their parent directories owned by root and not writable by group or others. Before upgrading the driver, stop workloads and then stop NPU Exporter.
| Default host path | Purpose | Mount access |
|---|---|---|
/usr/local/Ascend/driver | Driver libraries | Read-only |
/usr/local/dcmi | DCMI libraries | Read-only |
/sys | Device information | Read-only |
/run/containerd | Containerd and CRI socket access | Read-only directory mount |
/etc/localtime | Node timezone | Read-only |
/var/log/mindx-dl/npu-exporter | Exporter logs | Writable |
test -d /usr/local/Ascend/driver
test -d /usr/local/dcmi
test -S /run/containerd/containerd.sock
Removing the component does not remove host logs. The container root filesystem is read-only, /tmp uses emptyDir, and the ServiceAccount token is not mounted. These settings do not remove the privileged container’s host access.
Optional: PPU Components
ppu-device-plugin is optional and disabled by default. It is available in amd64 Enterprise, AI Platform, and their Slim packages; arm64 packages contain neither this component nor its images. This package uses PPU Device Plugin Chart 0.0.5 and plugin v1.0.6 to deploy the device plugin and PPU monitor in hami-system. Avoid duplicate installations.
Node Preparation and Configuration
Install the PPU driver and runtime appropriate for the node, confirm that the node can access its PPU devices, then add the node label:
kubectl label nodes <PPU_NODE> alibabappu=on --overwrite
Enable Alibaba PPU in HAMi and keep the plugin and monitoring enabled. Add the following to package-values.yaml:
hami:
  devices:
    alibaba:
      enabled: true
ppu-device-plugin:
  nodeSelector:
    alibabappu: "on"
  plugin:
    enabled: true
  monitor:
    enabled: true
    service:
      enabled: true
The PPU Chart creates a separate ConfigMap by default. Before deployment, confirm that the resource names and partitioning configuration in ppu-device-plugin.config.data.alibaba match the HAMi scheduler configuration. Do not copy the Ascend ConfigMap configuration directly to PPU. Default resource names include alibaba.com/ppu, alibaba.com/ppu-memory, and alibaba.com/gpu-core. RPM does not support PPU in this version.
Deployment
For an initial deployment, select both hami and ppu-device-plugin. If HAMi is already installed with Alibaba configuration enabled, select only ppu-device-plugin:
zarf package deploy hami-ai-platform-v0.0.6-airgap-amd64.tar.zst \
  --components=hami,ppu-device-plugin \
  --values=package-values.yaml \
  --confirm
Monitoring Integration
Clusters managed by Kantaloupe: Enable Alibaba PPU monitoring on the control plane, including when only member clusters have PPU devices. Merge the following into the existing hami-ai-platform configuration and redeploy the hami-ai-platform component. For a direct Helm upgrade, omit that top-level key and preserve the existing configuration.
hami-ai-platform:
  monitoring:
    enabled: true
    vendorServiceMonitor:
      enabled: true
      enableAlibabaPPUServicemonitor: true
By default, the platform discovers Services in hami-system labeled app=ppu-vgpu-monitor and component=vgpu-monitor and scrapes their metrics port. The default Service is ppu-device-plugin-monitor, with port 31992 targeting container port 9394.
Standalone monitoring without Kantaloupe: Configure a Prometheus ServiceMonitor or VictoriaMetrics VMServiceScrape for the same Service to scrape /metrics on the metrics port. Monitoring object labels must match the monitoring system’s selector. The PPU Chart has no ServiceMonitor switch. Do not create two scrape configurations for the same Service.
Verification
kubectl get nodes -l alibabappu=on
kubectl -n hami-system get daemonsets ppu-device-plugin ppu-device-plugin-monitor
kubectl -n hami-system rollout status daemonset/ppu-device-plugin --timeout=180s
kubectl -n hami-system rollout status daemonset/ppu-device-plugin-monitor --timeout=180s
kubectl -n hami-system get pods -o wide
kubectl -n hami-system get endpointslice -l kubernetes.io/service-name=ppu-device-plugin-monitor
kubectl describe node <PPU_NODE>
For both DaemonSets, DESIRED and READY should equal the expected PPU node count and be greater than zero. After license activation and confirmation that nodes have registered PPU resources, run a workload requesting PPU resources to verify allocation and device access.
Query up{job="ppu-vgpu-monitor",namespace="hami-system"} and hami_host_gpu_utilization_ratio{zone="vGPU"} in Prometheus to check scraping and raw metrics. For Kantaloupe, also check the member cluster’s raw metrics and kantaloupe_gpu_core_used{vendor="alibaba-ppu",cluster="<member-cluster-name>"} on the control plane. Zero utilization can indicate an idle device. Ready Pods or nonempty platform metrics alone do not prove that real metrics have been collected; verify the raw metrics and scrape targets.
The platform’s current PPU temperature and power rules use placeholder values, which do not represent real temperature or power consumption. If raw metrics are missing, check the node driver, plugin, and monitor logs. For scrape failures, check Service labels, ports, EndpointSlices, ServiceMonitor selectors, duplicate scraping, and network policies.
Optional: Resource Pool Management (RPM)
rpm is not installed by default. It is available in Enterprise, AI Platform, and their Slim packages. The component installs HAMi Enterprise CRD Chart 0.4.2 followed by Resource Pool Manager Chart 0.0.6 in hami-system; the manager image is v0.0.2.
Before installation, confirm Kubernetes ≥ 1.30, HAMi uses extender scheduling mode, and the scheduler device ConfigMap exists in hami-system. RPM currently supports NVIDIA, Ascend, and Hygon; enable at least one device type. This version does not support PPU resource pool management.
Configuration
rpm:
  crds: {}
  manager:
    hami:
      existingConfigMap: hami-scheduler-device
      schedulerName: hami-scheduler
    devices:
      nvidia:
        enabled: true
      ascend:
        enabled: false
      hygon:
        enabled: false
Select device switches to match the hardware and HAMi device configuration. Override the corresponding settings if the existing HAMi ConfigMap or scheduler has a different name. RPM reads the cluster’s device ConfigMap during installation or upgrade. After changing scheduler device configuration, redeploy rpm to update webhook rules.
Deployment
Select hami,rpm when installing HAMi and RPM together. If HAMi is already installed, select only rpm. Select platform and Gateway components as described earlier.
zarf package deploy hami-ai-platform-v0.0.6-airgap-amd64.tar.zst \
  --components=hami,rpm \
  --values=package-values.yaml \
  --confirm
Verification
zarf tools helm list -n hami-system
kubectl -n hami-system get deployments,pods
kubectl get crd | grep hami.io
After confirming that both Chart releases and the manager Pod are healthy, verify resource pools, access authorization, and workload admission behavior. Offline rendering cannot read the target cluster’s ConfigMap and does not replace validation of an actual installation. The CRD Chart retains CRDs and their custom resources by default; uninstalling RPM does not delete this data.
Monitoring Integration
Monitoring is optional. If the cluster already has compatible Prometheus or VictoriaMetrics monitoring, connect it using the selectors below. To install the bundled kube-prometheus-stack, select both monitoring components:
zarf package deploy hami-ai-platform-v0.0.6-airgap-amd64.tar.zst \
  --components=prometheus-crds,prometheus \
  --values=package-values.yaml \
  --confirm
Confirm that the metrics system can scrape HAMi, DCGM-Exporter, NPU Exporter, or PPU monitor metrics for the selected hardware. The v0.0.6 air-gapped package defaults to hami.legacyMetrics=false; the table below uses current metric names. Before checking that metrics are nonempty, confirm that the corresponding scrape targets report up=1.
For Prometheus, ServiceMonitor.metadata.labels must match Prometheus.spec.serviceMonitorSelector; otherwise, Prometheus will not scrape these metrics.
For VictoriaMetrics Operator, VMAgent.spec.serviceScrapeSelector selects VMServiceScrape.metadata.labels. Also check serviceScrapeNamespaceSelector. When converting from ServiceMonitor, confirm that the corresponding VMServiceScrape has been created.
Verify Metrics Collection
| Exporter | Query Metric | Expected Result |
|---|---|---|
| dcgm-exporter | DCGM_FI_DEV_GPU_UTIL | Nonempty result |
| hami-exporter | hami_host_gpu_utilization_ratio | Nonempty result |
| hami-device-plugin-exporter | hami_gpu_core_allocated_ratio | Nonempty result |
In addition to raw Exporter metrics, query kantaloupe_gpu_temp to verify Kantaloupe service metrics for NVIDIA and other applicable devices. For PPU, check raw utilization and memory metrics and the corresponding kantaloupe_gpu_core_used and kantaloupe_gpu_mem_used instead. The platform’s current PPU temperature and power rules use placeholder values; do not use kantaloupe_gpu_temp or kantaloupe_gpu_power to assess real temperature, power consumption, or successful monitoring integration.
License Acquisition
Start license activation once the HAMi core and required platform services are ready. Optional GPU Operator, Ascend, and monitoring components need not be installed first.
Use either method below to obtain the license request information. If the HAMi AI Platform site is not yet accessible, use the collection script.
Use HAMi AI Platform
-
Sign in to HAMi AI Platform with a platform administrator account.
-
Open License and System Information .
-
Follow the instructions on the page to obtain the license request information.
Run the Collection Script
The collection script requires kubectl and jq:
# Download and run the script
curl -fsSL https://public.hami.run/collect-hami-license-info.sh | bash

# Run a local copy provided with the delivery materials
bash collect-hami-license-info.sh
The command outputs JSON in the following format:
{
  "esn": "96565d61-986a-4918-aafb-448ff6e3746b",
  "deviceInstances": [
    {
      "uuid": "GPU-ceee905d-48ac-93de-a81b-17c00e1e5e02",
      "deviceType": "NVIDIA A10"
    }
  ]
}
Send the license request information to Dynamia.ai sales, pre-sales, or delivery personnel, then complete activation as instructed.
Post-Activation Verification
kubectl -n hami-system get pods
kubectl describe node <gpu-node>
kubectl get events --field-selector involvedObject.name=hami-license -n hami-system
kubectl get nodes -o custom-columns='NODE:.metadata.name,LICENSE:.metadata.annotations.hami\.io/nvidia-license'
A LicenseValid event indicates that license validation succeeded. Confirm that the selected component Pods are Running or Completed and that accelerator resources are registered on the managed nodes.
HAMi AI Platform Verification
# 1. Pod Status
kubectl -n kantaloupe-system get pods

# 2. Service Accessibility
kubectl -n kantaloupe-system get svc
After the HAMi AI Platform service is exposed, open the site and confirm that the frontend and backend are working normally.
Create Workload
On the console Workload page, create an application such as gpu-burn. In an air-gap environment, its image must already be in the relevant Zarf package or an accessible internal registry. For Zarf image rewriting, label the workload Namespace zarf.dev/agent: mutate.
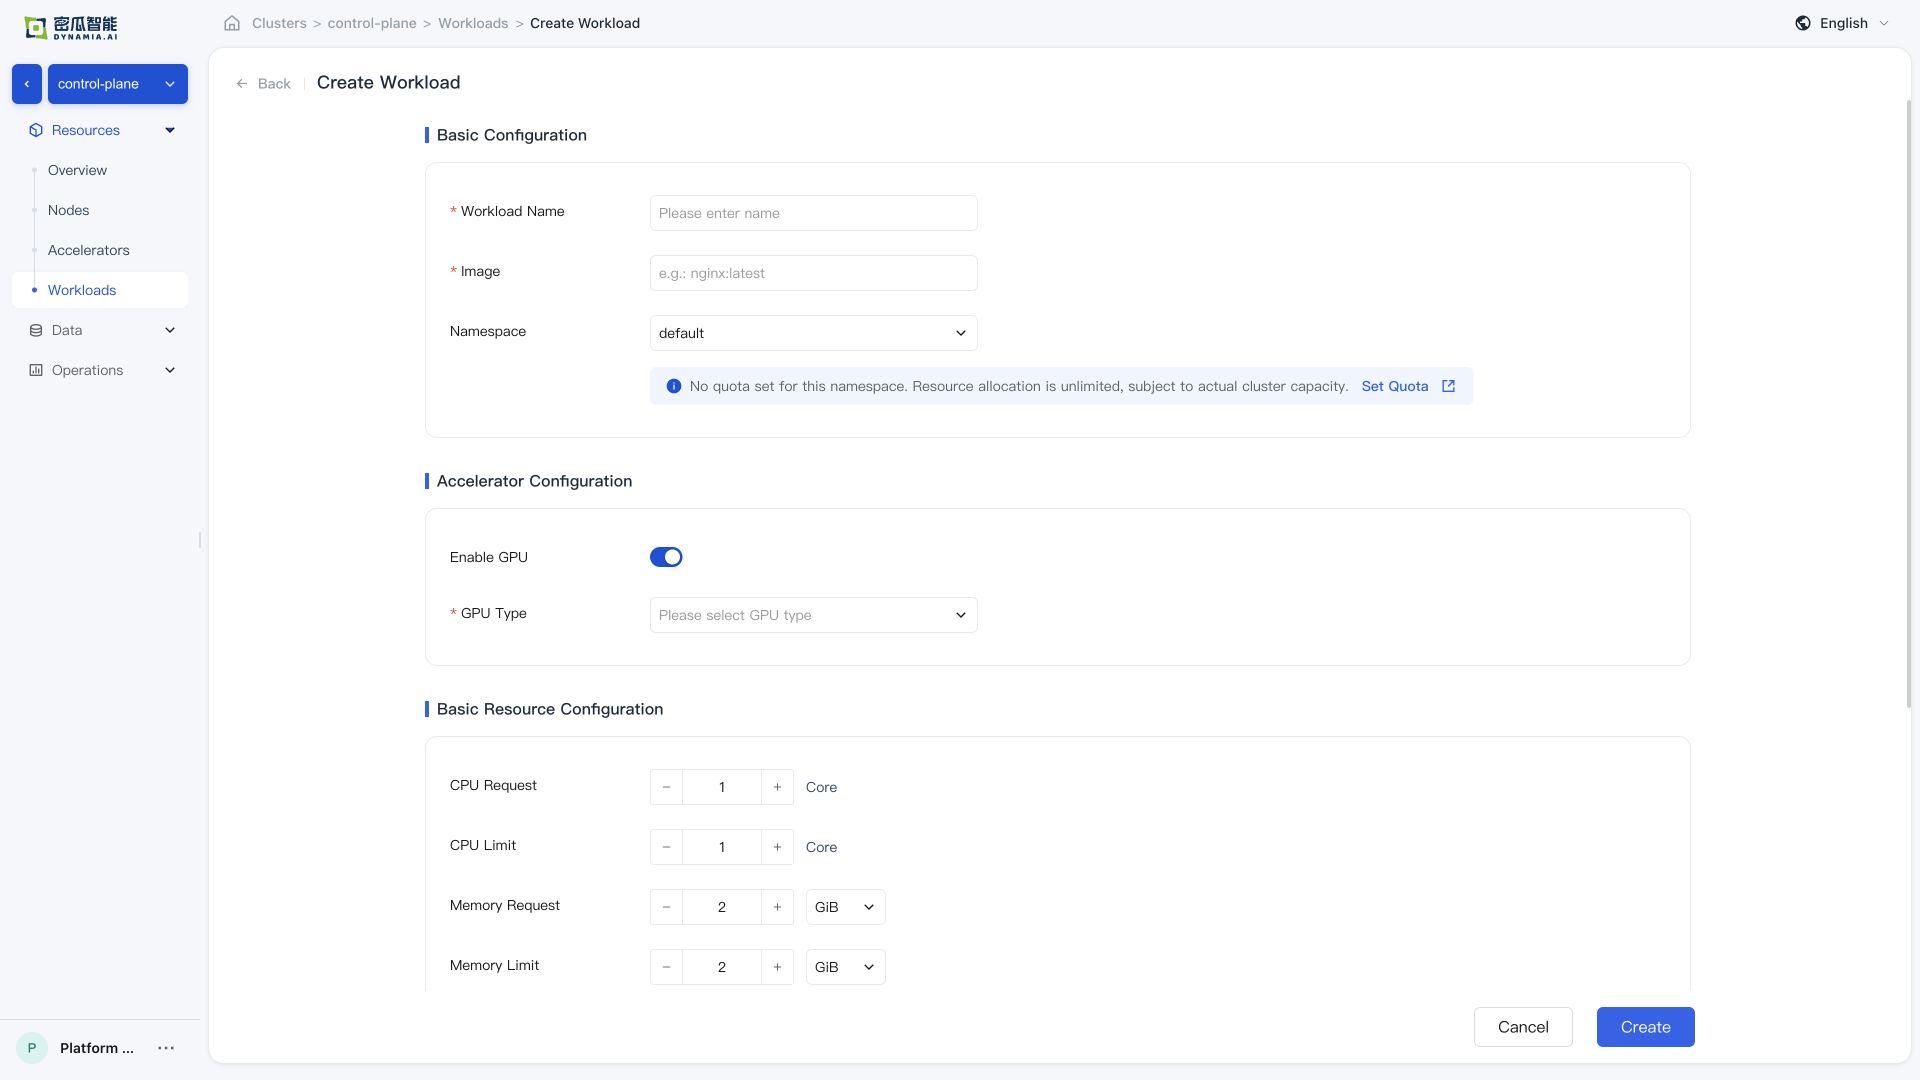
After creation, confirm that the following verification items all pass:
-
Creation successful , no errors in the console
-
Workload list : application status, search, list metrics, and monitoring panels (GPU SM / GPU MEM / CPU / Memory) are normal; time switching and charts meet expectations
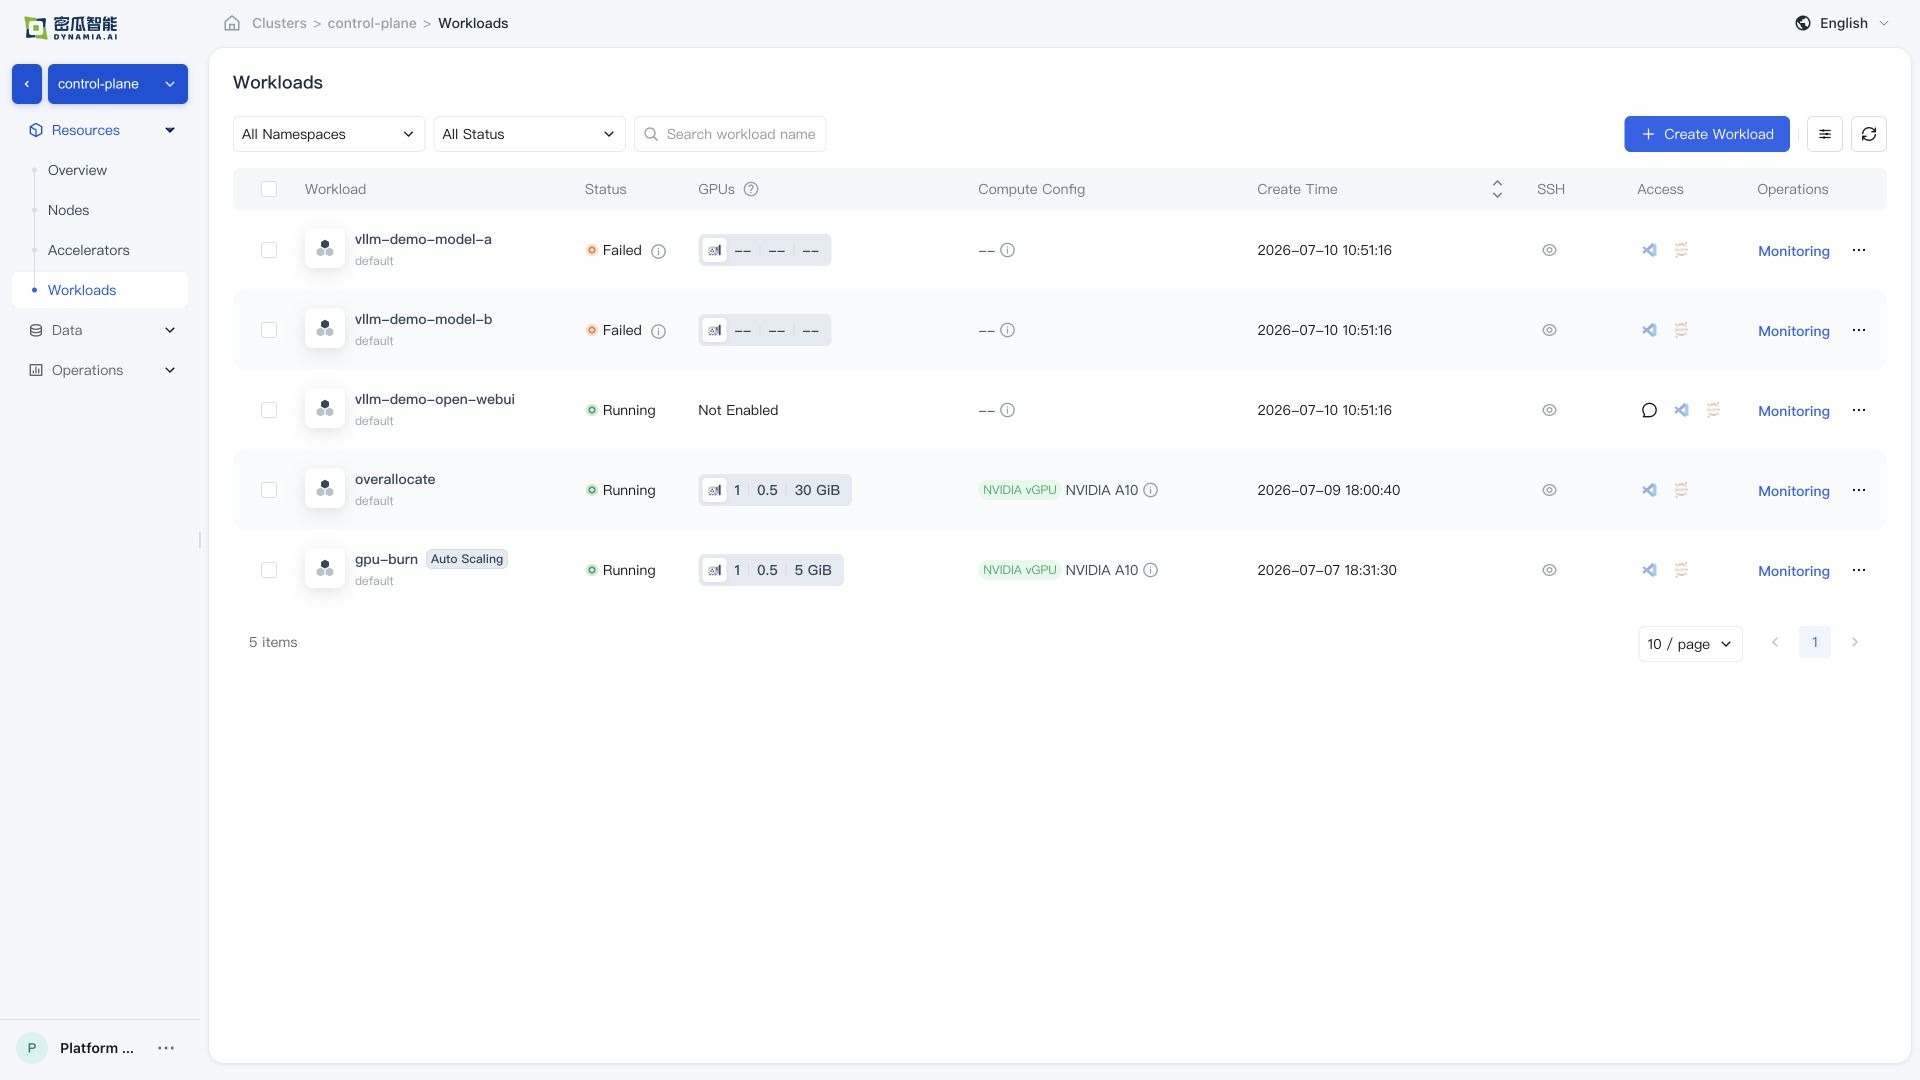
- Application details : basic information, resource overview, and monitoring data are normal; navigating from the detail page to the GPU / Node page, resource overview and monitoring data are normal
Sample Workload Verification
The full amd64 outer package includes independent GPU Burn v0.0.2 and vLLM Qwen v0.0.4 Zarf sample packages; Slim does not include samples. Their versions are independent of main package v0.0.6. Verify the core components and real device allocation before deploying the samples. These two NVIDIA samples create workloads without a separate kubectl apply. Before deployment, confirm that the sample package may clean up resources with the same names left by earlier versions in default. vLLM Ascend is a separately provided arm64 image package and does not deploy workloads automatically.
GPU Burn Verification
zarf package deploy zarf-package-hami-example-gpu-burn-amd64-v0.0.2.tar.zst --confirm
After deployment, check the Deployment / Pod status:
kubectl -n hami-example get deploy turbo-gpu-burn
kubectl -n hami-example get pods -l app=turbo-gpu-burn
kubectl -n hami-example logs -l app=turbo-gpu-burn --tail=50
This sample creates hami-example/turbo-gpu-burn Deployment; clean it up as needed after verification:
kubectl -n hami-example delete deploy turbo-gpu-burn
vLLM + Qwen Verification
zarf package deploy zarf-package-hami-example-vllm-qwen-amd64-v0.0.4.tar.zst --confirm
After deployment, check the inference service status:
kubectl -n hami-example get deploy vllm-qwen3
kubectl -n hami-example get pods -l app=vllm-qwen3
kubectl -n hami-example get svc vllm-qwen3-webui
Once the Pod is ready, access Open WebUI at http://<node-ip>:30081/openwebui. Confirm that your firewall and cluster network policy allow port 30081.
# Get cluster node IP (any reachable node is fine)
kubectl get nodes -o wide

# Access via browser
# http://<node-ip>:30081/openwebui
Open WebUI is automatically connected to the vLLM sidecar in the same Pod; open the page to start interacting.
If the Pod remains Pending, first check whether the license is activated, whether GPU nodes are labeled with gpu=on, and whether the node GPU drivers are normal.
Troubleshooting
For deployment failures, inspect Pods, events, and Zarf package status. Use zarf tools helm to inspect Helm releases. Diagnostic files may contain cluster configuration and logs; review them for sensitive information before sharing and do not include Secrets.
kubectl get pods -A | grep -E 'hami|gpu-operator|prometheus|vllm|gpu-burn'
kubectl get events -A --sort-by=.lastTimestamp | tail -50
zarf package list
Collect Kubernetes and GPU inventory with collect-cluster-info.sh; see COLLECT-CLUSTER-INFO.md. First install tools to provide jq. Set PACKAGE to your main package below: the AI Platform filename is hami-ai-platform-v0.0.6-airgap-amd64.tar.zst; Slim uses the corresponding -slim- filename. For arm64, replace amd64 in both CLI and package names. Preserve the target kubeconfig when using sudo.
KUBECONFIG_PATH="${KUBECONFIG:-$HOME/.kube/config}"
COLLECTOR_PATH="$PWD/collect-cluster-info.sh"
ROOT_PATH="/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin:/snap/bin"
PACKAGE=./hami-ai-platform-v0.0.6-airgap-amd64.tar.zst

sudo env PATH="$ROOT_PATH" sh -c 'command -v kubectl >/dev/null'
sudo env KUBECONFIG="$KUBECONFIG_PATH" PATH="$ROOT_PATH" \
  ./zarf-linux-amd64 package deploy "$PACKAGE" \
  --components=tools --confirm
sudo env PATH="$ROOT_PATH" sh -c 'command -v jq >/dev/null'
sudo env KUBECONFIG="$KUBECONFIG_PATH" PATH="$ROOT_PATH" \
  "$COLLECTOR_PATH" > cluster-info.json
sudo /usr/local/bin/jq empty cluster-info.json
Common Issues
| Symptom | Possible Cause | Resolution |
|---|---|---|
| Image pull fails | The Namespace or workload is not labeled zarf.dev/agent: mutate, the Pod was created before the label was added, or the image is absent from the Zarf package. | Check Namespace or workload labels, the Zarf Agent webhook and logs, and the Pod’s actual image reference. Confirm that the image is included in the package. Recreate the Pod after correcting labels. |
hami-device-plugin Pod is Pending or missing | The node is not labeled gpu=on. | Run kubectl label nodes <node> gpu=on. |
hami-device-plugin Pod repeatedly restarts | It conflicts with NVIDIA GPU Operator’s default device plugin. | Confirm that GPU Operator has devicePlugin.enabled=false. |
| HAMi metrics are unavailable | Prometheus or VictoriaMetrics selectors do not match monitoring object labels. | Check the monitoring component’s selectors and confirm that they match the HAMi ServiceMonitor labels. |
nvidia-smi reports an error | The GPU driver is not ready. | Check driver Pod status in the gpu-operator Namespace. |
Sample workload remains Pending | The license is not activated, GPU capacity is insufficient, or node labels are missing. | Check license status, GPU node labels, available GPU resources, and kubectl describe pod events. |
Gateway has no ingress address | Gateway API or Envoy Gateway CRDs are not ready, the Envoy Gateway release is unhealthy, or the Envoy Service type is unsuitable for the cluster. | Check that all 20 relevant CRDs are Established, run zarf tools helm status eg -n envoy-gateway-system, and inspect Gateway conditions and the Envoy Service. Do not retry by uninstalling a CRD release or deleting CRDs. |
Limitations of Installing Components with Zarf
Control the Image Rewrite Scope Explicitly with Labels
We recommend initializing Zarf with zarf init --agent-mutation-policy=labeled. This policy rewrites only resources labeled zarf.dev/agent: mutate, or resources in a namespace with that label. An individual workload that must retain its original image reference can be labeled zarf.dev/agent: ignore, and a resource label takes precedence over the namespace label. This allows image rewriting to be controlled per resource, even within the same cluster or namespace, without having the Agent manage every application namespace by default. Only images included in the Zarf package can be rewritten and pulled in an offline environment. After changing labels, recreate existing Pods because they are not updated automatically.
Manage Each Set of Resources Through a Single Delivery Pipeline
Zarf manages the chart releases in a package through Helm. Managing the same Kubernetes resources in parallel through another native Helm workflow can still cause release ownership, field ownership, and upgrade ordering conflicts. Continue routine upgrades with a newer Zarf package. If existing resources must be transferred to Zarf, review the release and resource scope before using --take-ownership. Use --force-conflicts only for Server-Side Apply field conflicts that you have confirmed may be overwritten; it should not be used as a routine installation option.
Support
-
Email: [email protected]
-
Sales / technical support: 400-026-7800
-
Customers with active commercial agreements should submit support requests through their dedicated support channel.