HAMi AI Platform Online Deployment Guide
This guide is intended for SREs and platform engineers. It explains how to deploy HAMi AI Platform on a Kubernetes cluster, integrate it with foundational components such as HAMi, Prometheus, NVIDIA GPU Operator, and Gateway API, and verify that the deployment works as expected.
⚠️ Installation ≠ Activation
After the Helm Charts are installed, the platform services can start. HAMi GPU virtualization and scheduling require license activation.
Installation itself does not require a license. Complete the software deployment first, then apply for and import the license.
Without activation, vGPU partitioning and scheduling are unavailable, and functional verification will fail.
Prerequisite Checks
-
Use a Kubernetes version supported by the selected Charts: HAMi requires Kubernetes ≥ 1.18; Ascend and PPU require ≥ 1.20; RPM requires ≥ 1.30. Provide an available default StorageClass. The administration host needs kubectl and Helm.
-
Prepare the NVIDIA driver and NVIDIA Container Toolkit on NVIDIA nodes.
-
Prepare the vendor driver, firmware, and runtime on Ascend nodes. Prepare the PPU driver and runtime on amd64 PPU nodes.
-
Disable NVIDIA GPU Operator’s default device plugin when HAMi supplies the NVIDIA device plugin. Set devicePlugin.enabled=false in the GPU Operator Helm values.
-
Before enabling monitoring integrations that create ServiceMonitor or PrometheusRule resources, confirm that the required
monitoring.coreos.comCRDs exist. If they are missing, follow the monitoring stack section below to install a compatible monitoring stack before installing GPU Operator or platform components that create these resources. Reuse an existing compatible Prometheus or VictoriaMetrics setup where available; clusters that do not enable monitoring do not need to install a monitoring stack.
kubectl cluster-info
kubectl version
kubectl get nodes -o wide
kubectl get storageclass
Online Installation
Before running the commands below, confirm that the current kubeconfig context points to the target cluster. Keep the values file for each Chart under version control. Contact Dynamia.ai technical support for access to commercial Charts, mainland China image registries, and production values.
Install HAMi Enterprise
Install the HAMi core first. This command uses the published GHCR Chart 2.10.0-r4; the administration host must be able to access GHCR, and cluster nodes must be able to pull the required images. Create hami-enterprise-values.yaml with the minimum configuration below so that HAMi creates the hami-scheduler-device ConfigMap used by the Ascend and RPM examples. Merge the configuration for the selected devices into this file, preserve all other required values, and retain the complete file for future upgrades.
fullnameOverride: hami
helm install hami \
  oci://ghcr.io/dynamia-ai/charts/hami-enterprise \
  --version 2.10.0-r4 \
  --namespace hami-system \
  --create-namespace \
  -f hami-enterprise-values.yaml
See the HAMi Helm Chart Values Reference for the complete configuration.
For non-NVIDIA devices, enable the corresponding vendor under devices in the HAMi values. Ascend nodes require at least:
devices:
  ascend:
    enabled: true
    hamiVnpuCore: true
Install NVIDIA GPU Operator (NVIDIA Nodes Only)
NVIDIA GPU Operator is optional. If the nodes already have a compatible driver, NVIDIA Container Toolkit, and runtime configuration, you can skip it. See the HAMi NVIDIA GPU node prerequisites for the node setup and GPU Operator values. When installing or reusing GPU Operator, disable its bundled device plugin (devicePlugin.enabled=false) and CDI (cdi.enabled=false). This HAMi Enterprise deployment uses scheduler.useDownward, which is incompatible with CDI. Assess running GPU workloads before changing CDI settings on an existing cluster.
helm repo add nvidia https://helm.ngc.nvidia.com/nvidia && helm repo update

helm install --wait --generate-name \
  -n gpu-operator --create-namespace \
  nvidia/gpu-operator \
  --set devicePlugin.enabled=false \
  --set dcgmExporter.serviceMonitor.enabled=true \
  --set cdi.enabled=false \
  --version=v25.10.1
Enable GPU Nodes
The HAMi NVIDIA device plugin starts on nodes labeled gpu=on. Apply this label to NVIDIA nodes that HAMi should manage. Ascend components use their own nodeSelector; gpu=on is not their selection rule.
kubectl label nodes <node-name> gpu=on
Install the Ascend Device Plugin (Ascend Nodes Only)
Install the Ascend device plugin after the HAMi core is ready and devices.ascend.enabled and devices.ascend.hamiVnpuCore are enabled. Avoid installing duplicate device plugins. The plugin reuses the hami-scheduler-device ConfigMap created by HAMi. Save the following configuration as ascend-device-plugin.yaml.
nameOverride: "ascend-device-plugin"
fullnameOverride: "ascend-device-plugin"
image:
  repository: ghcr.io/dynamia-ai/ascend-device-plugin
  tag: "v1.4.2"
config:
  create: false
  existingDeviceConfigMapName: hami-scheduler-device
helm install ascend-device-plugin \
  oci://ghcr.io/dynamia-ai/charts/ascend-device-plugin \
  --version 0.2.2 \
  --namespace hami-system \
  -f ascend-device-plugin.yaml
Install the PPU Device Plugin and Monitor (amd64 PPU Nodes Only)
This section uses PPU Device Plugin Chart 0.0.5 and plugin v1.0.6, which support amd64 only. Install the PPU driver and runtime appropriate for the nodes, and confirm that the nodes can access the PPU devices. Avoid installing duplicate device plugins.
Prepare the Nodes and HAMi Configuration
kubectl label nodes <PPU_NODE> alibabappu=on --overwrite
Merge the following configuration into hami-enterprise-values.yaml, preserving the rest of the file. For a new installation, use the HAMi installation command above. For an existing installation, run the upgrade command below with the complete values file.
devices:
  alibaba:
    enabled: true
helm upgrade hami \
  oci://ghcr.io/dynamia-ai/charts/hami-enterprise \
  --version 2.10.0-r4 \
  --namespace hami-system \
  -f hami-enterprise-values.yaml \
  --wait
Configure and Install the PPU Chart
Save the following content as ppu-device-plugin.yaml. The PPU Chart deploys both the device plugin and the monitor. This example sets the monitoring Service to ClusterIP for collection by an in-cluster monitoring system.
nameOverride: "ppu-device-plugin"
fullnameOverride: "ppu-device-plugin"

image:
  repository: ghcr.io/dynamia-ai/ppu-device-plugin
  tag: "v1.0.6"
  pullPolicy: IfNotPresent

nodeSelector:
  alibabappu: "on"

plugin:
  enabled: true

monitor:
  enabled: true
  service:
    enabled: true
    type: ClusterIP
The PPU Chart creates a separate ConfigMap by default. Before deployment, check that the resource names and partitioning settings under the native Chart value config.data.alibaba are consistent with the HAMi scheduler configuration. Do not copy the Ascend ConfigMap configuration directly. Default resource names include alibaba.com/ppu, alibaba.com/ppu-memory, and alibaba.com/gpu-core.
helm install ppu-device-plugin \
  oci://ghcr.io/dynamia-ai/charts/ppu-vgpu-device-plugin \
  --version 0.0.5 \
  --namespace hami-system \
  -f ppu-device-plugin.yaml \
  --wait
Connect PPU Monitoring
The PPU monitor exposes the hami-system/ppu-device-plugin-monitor Service with labels app=ppu-vgpu-monitor and component=vgpu-monitor. Its metrics Service port is 31992 and targets container port 9394. The PPU Chart has no ServiceMonitor switch. When connecting HAMi Enterprise to an existing Prometheus installation, confirm that the ServiceMonitor CRD exists before creating the object below. HAMi AI Platform users should follow the platform-specific instructions after this example.
apiVersion: monitoring.coreos.com/v1
kind: ServiceMonitor
metadata:
  name: ppu-vgpu-monitor
  namespace: hami-system
  labels:
    release: prometheus
spec:
  jobLabel: app
  namespaceSelector:
    matchNames:
      - hami-system
  selector:
    matchLabels:
      app: ppu-vgpu-monitor
      component: vgpu-monitor
  endpoints:
    - port: metrics
      path: /metrics
      interval: 15s
For HAMi Enterprise with an existing Prometheus installation, create the ServiceMonitor shown here. For HAMi AI Platform, use the Kantaloupe Chart PPU monitoring switches in the HAMi AI Platform Online Deployment Guide. These switches also enable the recording rules required by the platform. Do not additionally create the ServiceMonitor shown here, to avoid duplicate scraping. For the manual ServiceMonitor, adjust release: prometheus to match the actual Prometheus serviceMonitorSelector, and confirm that it discovers ServiceMonitors in hami-system. Save the file as ppu-servicemonitor.yaml and run kubectl apply -f ppu-servicemonitor.yaml. VictoriaMetrics users should configure the corresponding VMServiceScrape or confirm that the Operator has converted the ServiceMonitor; avoid scraping the same Service twice.
Verify the PPU Components
kubectl get nodes -l alibabappu=on
kubectl -n hami-system get daemonsets ppu-device-plugin ppu-device-plugin-monitor
kubectl -n hami-system rollout status daemonset/ppu-device-plugin --timeout=180s
kubectl -n hami-system rollout status daemonset/ppu-device-plugin-monitor --timeout=180s
kubectl -n hami-system get endpointslice -l kubernetes.io/service-name=ppu-device-plugin-monitor
kubectl describe node <PPU_NODE>
The DESIRED and READY counts for both DaemonSets should equal the expected number of PPU nodes and be greater than zero. Confirm that the nodes have registered PPU resources, then run a workload that requests those resources to verify allocation and device access.
In Prometheus, query up{job="ppu-vgpu-monitor",namespace="hami-system"} and confirm that each scrape target reports 1. Query hami_host_gpu_utilization_ratio{job="ppu-vgpu-monitor"} and hami_host_gpu_memory_used_bytes{job="ppu-vgpu-monitor"} to confirm that real device metrics are present. Zero utilization can indicate an idle device.
Install Resource Pool Management (RPM, Optional)
RPM requires Kubernetes ≥ 1.30 and HAMi extender scheduling. Install HAMi first and confirm that the hami-system/hami-scheduler-device ConfigMap exists. Enable at least one device type in RPM. The available configuration switches include NVIDIA, Ascend, and Hygon; actual device support depends on the manager image version. This version does not support PPU resource pool management.
kubectl -n hami-system get configmap hami-scheduler-device
Install the Resource Pool CRDs
helm install hami-enterprise-crds \
  oci://ghcr.io/dynamia-ai/charts/hami-enterprise-crds \
  --version 0.4.2 \
  --namespace hami-system \
  --wait

kubectl wait --for=condition=Established --timeout=60s \
  crd/gpudevices.resource.hami.io \
  crd/resourcepools.resource.hami.io \
  crd/resourcepoolbindings.resource.hami.io
Configure and Install Resource Pool Manager
Save the following configuration as rpm-values.yaml. This example enables NVIDIA only. For other devices, confirm support in the selected manager version before changing the devices switches, and ensure that the HAMi device configuration contains the corresponding resources.
image:
  repository: ghcr.io/dynamia-ai/resource-pool-manager
  tag: "v0.0.2"

hami:
  schedulerName: hami-scheduler
  existingConfigMap: hami-scheduler-device

devices:
  nvidia:
    enabled: true
  ascend:
    enabled: false
  hygon:
    enabled: false

webhook:
  tls:
    certgen:
      image:
        repository: registry.k8s.io/ingress-nginx/kube-webhook-certgen
        tag: v1.6.9
During installation, the manager Chart uses Helm lookup to read the scheduler device configuration from the target cluster. The administration host must be able to access that cluster. A local helm template run cannot replace this step.
helm install hami-resource-pool-manager \
  oci://ghcr.io/dynamia-ai/charts/hami-resource-pool-manager \
  --version 0.0.6 \
  --namespace hami-system \
  -f rpm-values.yaml \
  --wait
After changing the scheduler device configuration, upgrade Resource Pool Manager with the complete manager values file to keep admission rules aligned with that configuration. The CRD Chart retains CRDs and their custom resources by default; uninstalling RPM does not delete this data.
Verify RPM
helm list -n hami-system
kubectl -n hami-system rollout status deployment/hami-resource-pool-manager --timeout=180s
kubectl get crd gpudevices.resource.hami.io resourcepools.resource.hami.io resourcepoolbindings.resource.hami.io
kubectl get gpudevices,resourcepools
kubectl get resourcepoolbindings -A
Confirm that both Helm releases are installed successfully, the manager Deployment is ready, and the device inventory is correct. After configuring resource pools and access rules, verify ResourcePool, ResourcePoolBinding, and workload admission behavior. Pod readiness alone does not prove that resource pool authorization is effective.
In addition to HAMi, HAMi AI Platform uses Kubernetes Gateway API with Envoy Gateway as its default service exposure mechanism. If the cluster does not already provide Gateway API resources , check with kubectl api-resources | grep gateway.networking.k8s.io/v1, then install the Gateway API standard channel before continuing.
Install Envoy Gateway
If the cluster does not already have a Gateway API controller, install envoyproxy/envoy-gateway to expose services:
helm install eg \
  oci://docker.io/envoyproxy/gateway-helm \
  --version v1.6.2 \
  --namespace envoy-gateway-system \
  --create-namespace \
  --set global.images.envoyGateway.image=docker.io/envoyproxy/gateway:v1.6.2 \
  --set global.image.ratelimit.image=docker.io/envoyproxy/ratelimit:99d85510 \
  --set config.envoyGateway.gateway.controllerName=gateway.envoyproxy.io/gatewayclass-controller \
  --set config.envoyGateway.provider.type=Kubernetes
Install HAMi AI Platform
Before installing dynamia-ai/kantaloupe, the HAMi AI Platform service (referred to as kantaloupe below), combine the examples below into kantaloupe-values.yaml and replace the authentication and domain placeholders. Save the file, then run:
helm install kantaloupe \
  oci://dynamia-ai-registry.cn-hangzhou.cr.aliyuncs.com/public/charts/kantaloupe-chart \
  --version 0.21.3 \
  --namespace kantaloupe-system \
  --create-namespace \
  --set fullnameOverride=kantaloupe \
  -f kantaloupe-values.yaml
kantaloupe provides settings for feature flags, service exposure, and monitoring integration. Configure them as required. For the complete values reference, see kantaloupe Helm Chart Values Reference.
These examples use native Kantaloupe Chart values. Before installation, select the settings for your environment, merge them into kantaloupe-values.yaml, and replace the authentication and domain placeholders. Pass the file to the installation command with -f kantaloupe-values.yaml. Choose one service exposure option.
- Configure default platform administrator credentials
auth:
jwtSecret: "<JWT_SIGNING_SECRET>"
bootstrapAdminUsername: "bootstrap-platform-admin"
bootstrapAdminPassword: "<ADMIN_PASSWORD>"
bootstrapAdminFullName: "Platform Administrator"
- Expose Envoy Gateway through a NodePort Service and use an external load balancer (cloud-managed or self-managed) to forward Layer 4 traffic .
gateway:
  enabled: true
  hostnames:
    - your-domain.example.com
  apiserverCors:
    enabled: true
    allowCredentials: true
    allowOrigins:
      - https://your-domain.example.com
  envoy:
    service:
      ports:
        http:
          nodePort: 30080
        https:
          nodePort: 30443
      type: NodePort
  listeners:
    - name: http
      port: 80
      protocol: HTTP
    - name: https
      port: 443
      protocol: HTTPS
      tls:
        certificateRef:
          name: your-domain-tls-secret
        redirectFromHttp: true
- Use Envoy Gateway with a NodePort Service for a simple PoC
gateway:
  enabled: true
  listeners:
    - name: http
      port: 80
      protocol: HTTP
  envoy:
    service:
      type: NodePort
      ports:
        http:
          nodePort: 30080
- Use a LoadBalancer Service managed by a cloud provider or bare-metal load balancer controller
gateway:
  enabled: true
  hostnames:
    - your.domain
  listeners:
    - name: http
      port: 80
      protocol: HTTP
    - name: https
      port: 443
      protocol: HTTPS
      tls:
        certificateRef:
          name: your-tls-secret
        redirectFromHttp: true
  envoy:
    service:
      type: LoadBalancer
      ports:
        http: {}
        https: {}
- Override the Prometheus Query API address (default:
http://prometheus-kube-prometheus-prometheus.monitoring.svc.cluster.local:9090)
apiserver:
  prometheusAddr: http://your-prometheus-query-api.com:9090

controllerManager:
  prometheusAddr: http://your-prometheus-query-api.com:9090
Optional: Enable PPU monitoring
For PPU devices, install the PPU device plugin and monitor as described above, then merge these native values into kantaloupe-values.yaml:
monitoring:
  enabled: true
  vendorServiceMonitor:
    enabled: true
    enableAlibabaPPUServicemonitor: true
By default, the platform discovers Services in hami-system with the labels app=ppu-vgpu-monitor and component=vgpu-monitor, and scrapes their metrics port. The default Service is ppu-device-plugin-monitor, with Service port 31992 mapped to container port 9394. Confirm that the Prometheus ServiceMonitor selector selects the platform's alibaba-ppu-monitor.
Query the following metrics in Prometheus to verify successful scrapes and the presence of raw utilization and memory data:
up{job="ppu-vgpu-monitor",namespace="hami-system"}
hami_host_gpu_utilization_ratio{zone="vGPU"}
hami_host_gpu_memory_used_bytes{zone="vGPU"}
up should be 1; zero utilization can mean that a device is idle. In the control plane, also check the target cluster's raw metrics and the corresponding kantaloupe_gpu_core_used{vendor="alibaba-ppu"} and kantaloupe_gpu_mem_used{vendor="alibaba-ppu"} metrics. For member clusters, filter metrics with cluster="<member-cluster-name>". A Ready Pod or nonempty platform metrics alone does not prove that real device data is being collected.
The platform's current PPU temperature and power rules use placeholder values, not real temperature or power readings. If raw metrics are missing, check the node drivers and the plugin and monitor logs. If scrapes fail, check Service labels, ports, EndpointSlices, ServiceMonitor selectors, duplicate scrapes, and network policies.
Install the Monitoring Stack (When Needed)
Monitoring is optional. Install kube-prometheus-stack only if metrics are needed and the cluster does not already have a compatible Prometheus or VictoriaMetrics installation. Otherwise, connect the existing monitoring system as described below.
helm install prometheus \
  oci://ghcr.io/prometheus-community/charts/kube-prometheus-stack \
  --version 72.3.0 \
  --namespace monitoring \
  --create-namespace \
  --set alertmanager.enabled=false \
  --set grafana.enabled=false
Nodes and Monitoring
kubectl describe node <node-name>
kubectl api-resources --api-group=monitoring.coreos.com
For Prometheus, match ServiceMonitor.metadata.labels to Prometheus.spec.serviceMonitorSelector and check the namespace selector. For VictoriaMetrics Operator, VMAgent.spec.serviceScrapeSelector selects VMServiceScrape.metadata.labels; also check serviceScrapeNamespaceSelector and any ServiceMonitor conversion.
For PPU, also follow the component section to check raw utilization and memory metrics. Check that the relevant scrape targets report up=1, then query the current NVIDIA metrics and confirm that they return data:
-
DCGM_FI_DEV_GPU_UTIL -
hami_host_gpu_utilization_ratio -
hami_gpu_core_allocated_ratio
In addition to raw exporter metrics, query kantaloupe_gpu_temp to verify the Kantaloupe metrics for devices such as NVIDIA GPUs. For PPU devices, check raw utilization and memory metrics and the corresponding kantaloupe_gpu_core_used and kantaloupe_gpu_mem_used metrics instead. The platform's current PPU temperature and power rules use placeholder values; kantaloupe_gpu_temp and kantaloupe_gpu_power cannot verify real temperature or power readings, or successful monitoring integration.
License Acquisition
Start license activation once the HAMi core and required platform services are ready. Optional GPU Operator, Ascend, and monitoring components need not be installed first.
Use either method below to obtain the license request information. If the HAMi AI Platform site is not yet accessible, use the collection script.
Use HAMi AI Platform
-
Sign in to HAMi AI Platform with a platform administrator account.
-
Open License and System Information .
-
Follow the instructions on the page to obtain the license request information.
Run the Collection Script
The collection script requires kubectl and jq:
# Download and run the script
curl -fsSL https://public.hami.run/collect-hami-license-info.sh | bash

# Run a local copy provided with the delivery materials
bash collect-hami-license-info.sh
The command outputs JSON in the following format:
{
  "esn": "96565d61-986a-4918-aafb-448ff6e3746b",
  "deviceInstances": [
    {
      "uuid": "GPU-ceee905d-48ac-93de-a81b-17c00e1e5e02",
      "deviceType": "NVIDIA A10"
    }
  ]
}
Send the license request information to Dynamia.ai sales, pre-sales, or delivery personnel, then complete activation as instructed.
Post-Activation Verification
# 1. Check Pod status
kubectl -n hami-system get pods

# 2. Check GPU resources registered by the device plugin
kubectl describe node <gpu-node> | grep -A 5 "Capacity:"
# Expected: nvidia.com/gpu: <N> and nvidia.com/gpumem: <MB>

# 3. Check license events generated by the scheduler
kubectl get events --field-selector involvedObject.name=hami-license -n hami-system
Expected: all HAMi Pods are running, GPU resources are registered on GPU nodes, and the hami-license event reports that the license was validated successfully. Then open License and System Information in HAMi AI Platform and confirm that the license status and scope are correct.
HAMi AI Platform Verification
# 1. Pod Status
kubectl -n kantaloupe-system get pods

# 2. Service Accessibility
kubectl -n kantaloupe-system get svc
After the HAMi AI Platform service is exposed, open the site and confirm that the frontend and backend are working normally.
Create Workload
On the console Workload page, create an application such as gpu-burn. Make sure its image is available from a registry accessible to the cluster, then verify that the workload runs.
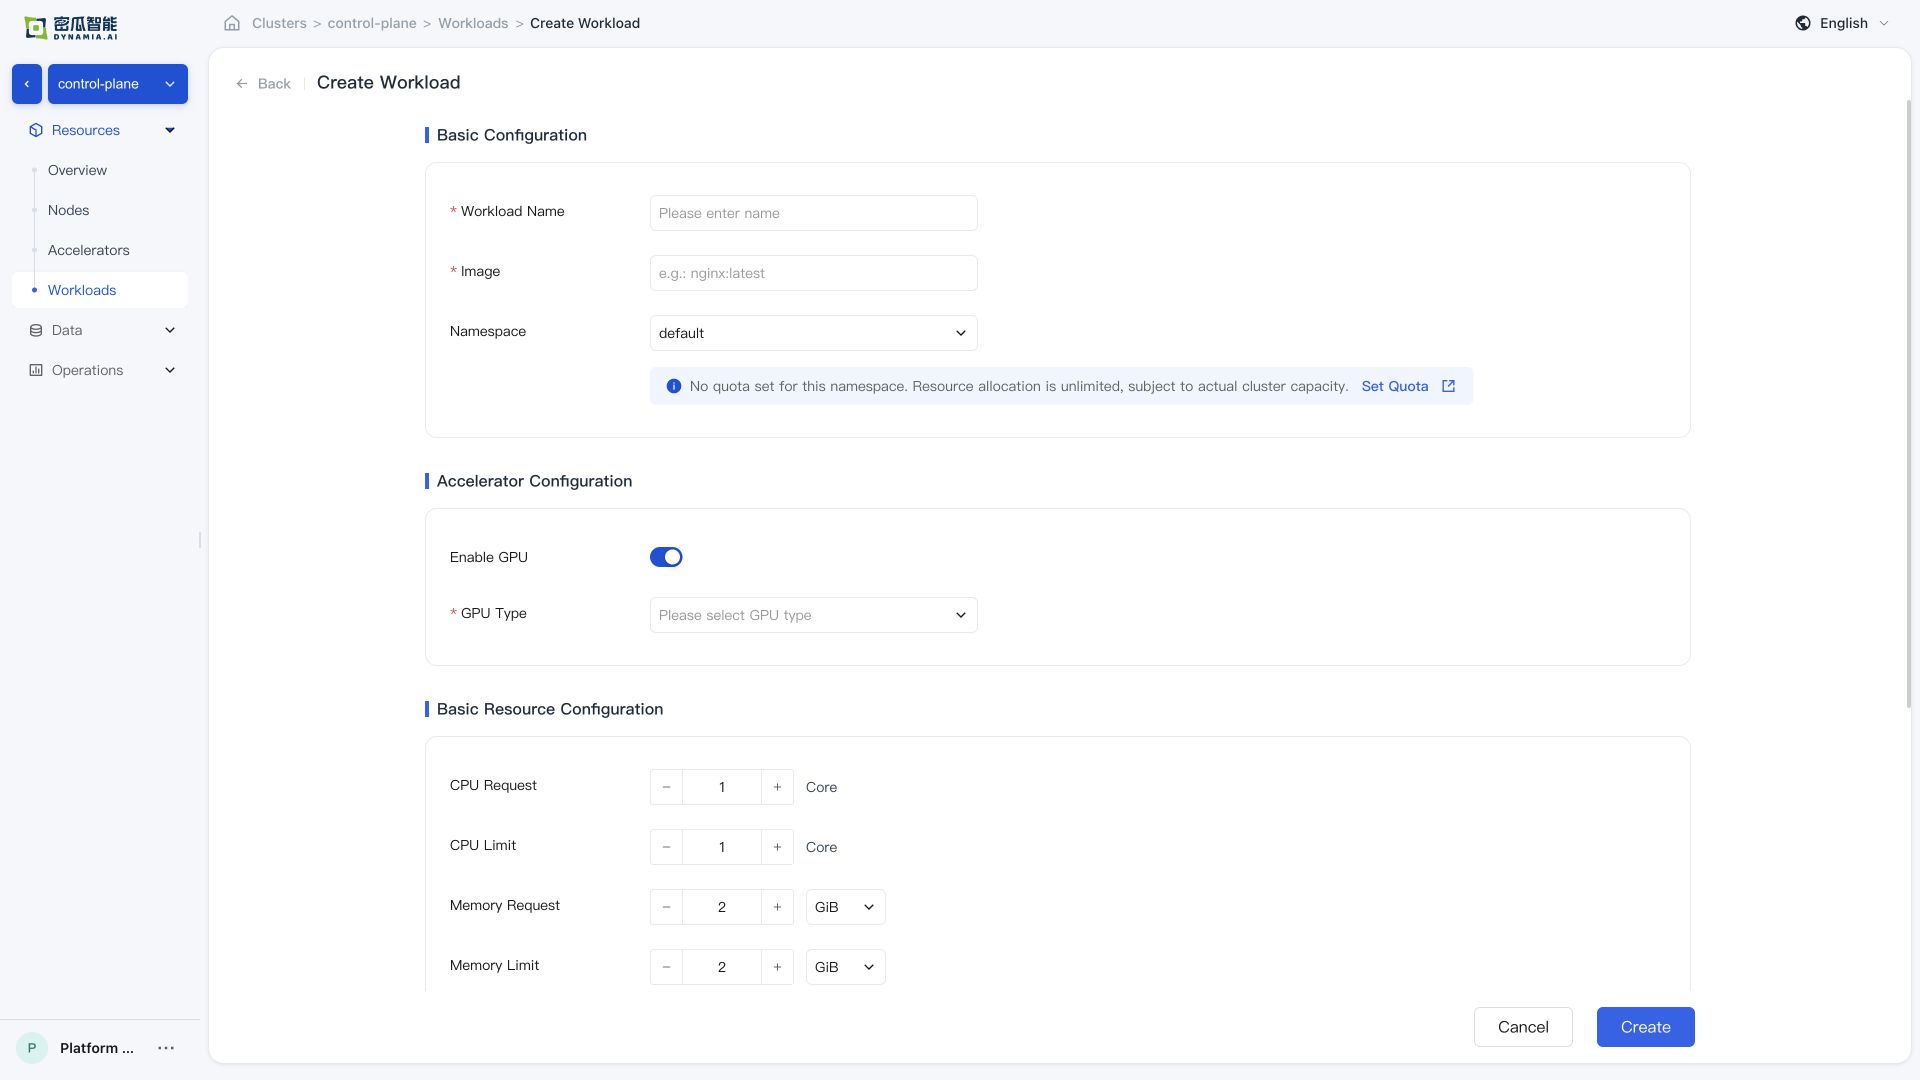
After creation, confirm that the following verification items all pass:
-
Creation successful , no errors in the console
-
Workload list : application status, search, list metrics, and monitoring panels (GPU SM / GPU MEM / CPU / Memory) are normal; time switching and charts meet expectations
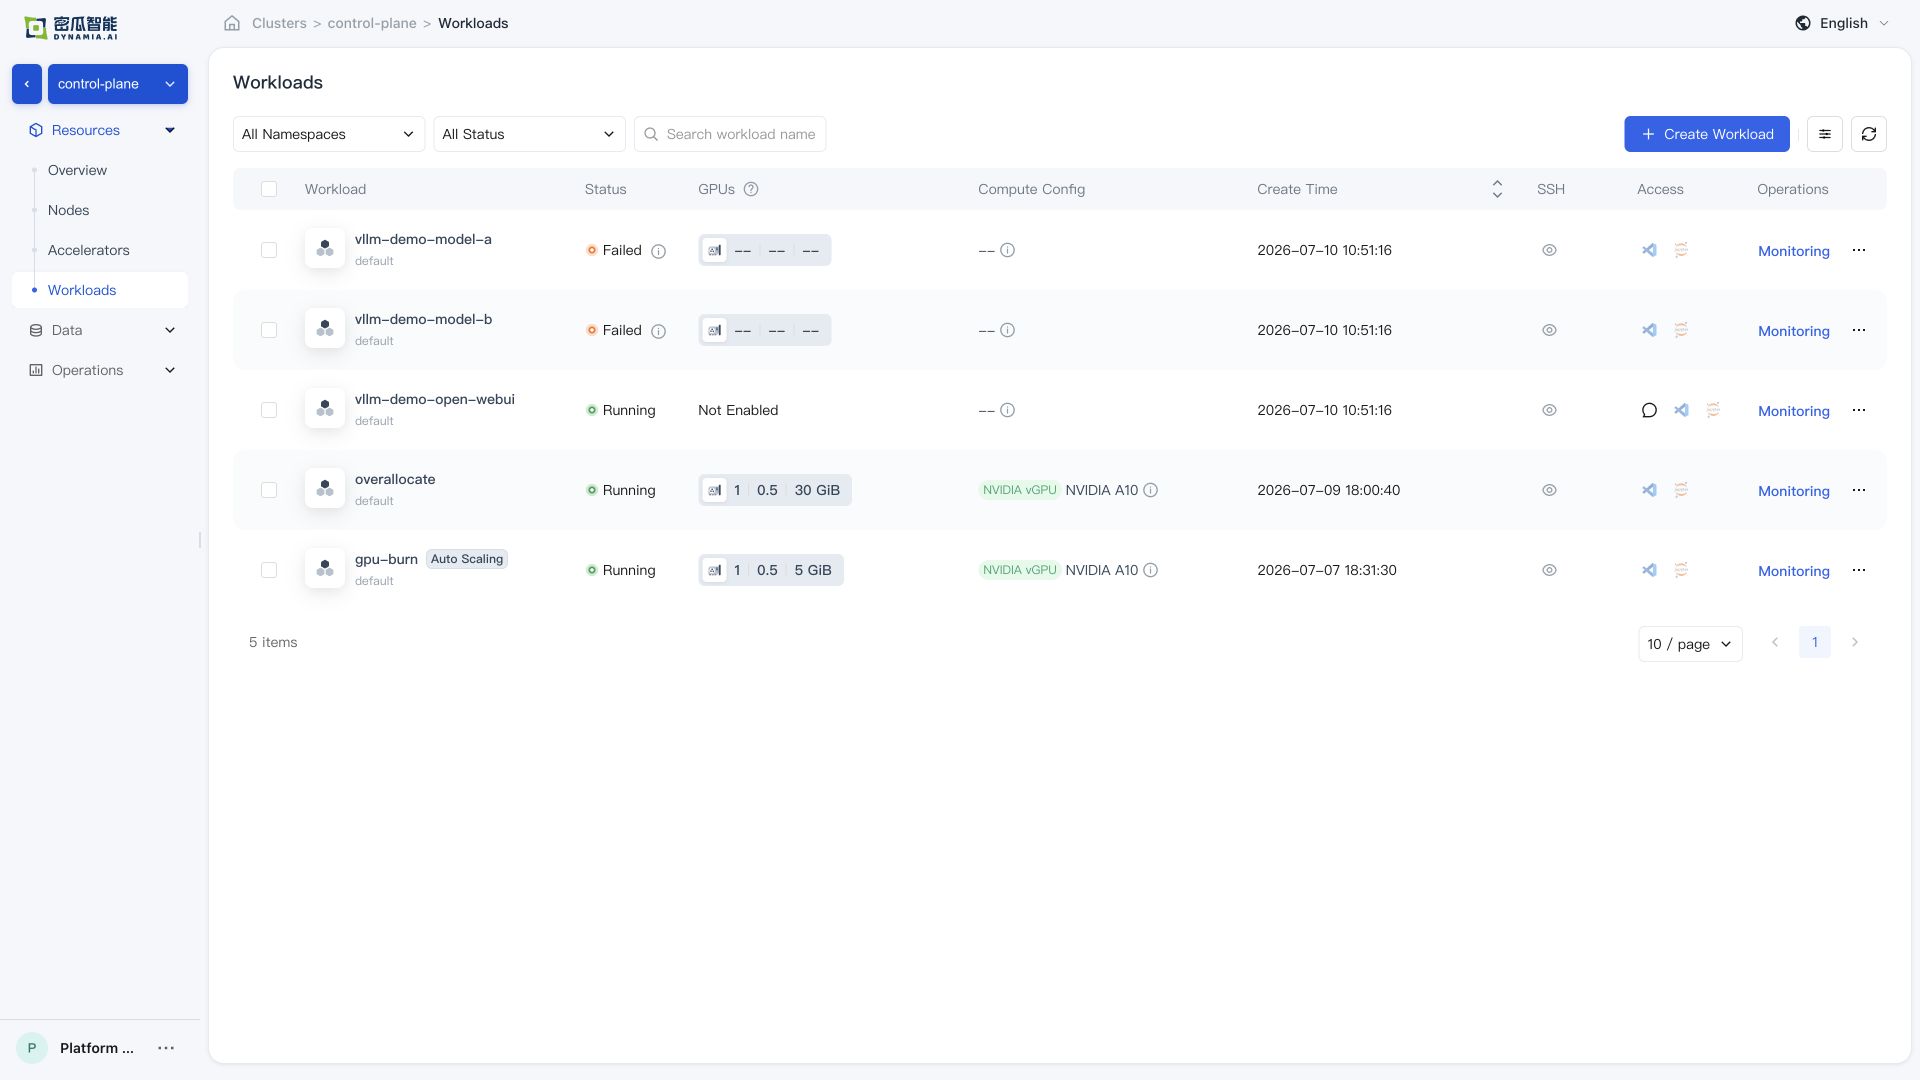
- Application details : basic information, resource overview, and monitoring data are normal; navigating from the detail page to the GPU / Node page, resource overview and monitoring data are normal
Online Sample Workload Verification
Before running this example, confirm that the target cluster can pull nvidia/cuda:12.4.0-base-ubuntu22.04. If the cluster uses a private registry, mirror the image first and update the image reference in the example.
kubectl delete pod hami-smoke --ignore-not-found

kubectl apply -f - <<'EOF'
apiVersion: v1
kind: Pod
metadata:
  name: hami-smoke
spec:
  restartPolicy: Never
  containers:
    - name: cuda
      image: nvidia/cuda:12.4.0-base-ubuntu22.04
      command: ["sh", "-c", "nvidia-smi && sleep 30"]
      resources:
        limits:
          nvidia.com/gpu: 1
          nvidia.com/gpumem: 2000
EOF

kubectl wait --for=condition=Ready pod/hami-smoke --timeout=180s
kubectl logs hami-smoke
If the Pod reaches Ready and the logs show GPU information, HAMi has scheduled the GPU and the NVIDIA runtime is available inside the container. Delete the test Pod after verification.
kubectl delete pod hami-smoke
Common Issues
| Symptom | Possible Cause | Resolution |
|---|---|---|
| Image pull fails | The node cannot reach the image registry, registry authentication is missing or invalid, or the image reference is incorrect | Inspect the Pod events and image reference, verify node DNS and network access to the registry, and configure the required image pull credentials. |
hami-device-plugin Pod is Pending or missing | The node is not labeled gpu=on | kubectl label nodes <node> gpu=on |
hami-device-plugin Pod is in CrashLoopBackOff | It conflicts with the default NVIDIA device-plugin | Disable the default NVIDIA device plugin. In the GPU Operator Helm values, set devicePlugin.enabled=false. |
| HAMi metrics are unavailable | The serviceMonitorSelector of the Prometheus resource does not match the labels on the ServiceMonitor resource | Align monitoring/prometheus-kube-prometheus-prometheus spec.serviceMonitorSelector with the labels on the HAMi ServiceMonitor, and check serviceMonitorNamespaceSelector. |
nvidia-smi reports an error | The GPU driver is not ready | Check the driver Pod status in the gpu-operator Namespace. |
Sample workload remains Pending | The license is not activated, GPU capacity is insufficient, or node labels are missing | Check the license, GPU node labels, and kubectl describe pod events. |
Gateway has no ingress address | Gateway API or Envoy Gateway CRDs are not ready, the Envoy Gateway release is unhealthy, or the Envoy Service type is unsuitable for the cluster | Check that the required Gateway API and Envoy Gateway CRDs are Established, then inspect the Envoy Gateway Helm release, Gateway conditions and Envoy Service. Do not delete CRDs as a retry step. |
Support
-
Email: [email protected]
-
Sales / technical support: 400-026-7800
-
Customers with active commercial agreements should submit support requests through their dedicated support channel.